
Whisper
Multilingual speech recognition and translation
97.8k|stable|v20250625
import whisper
model = whisper.load_model("turbo")
result = model.transcribe("audio.mp3")
print(result["text"])
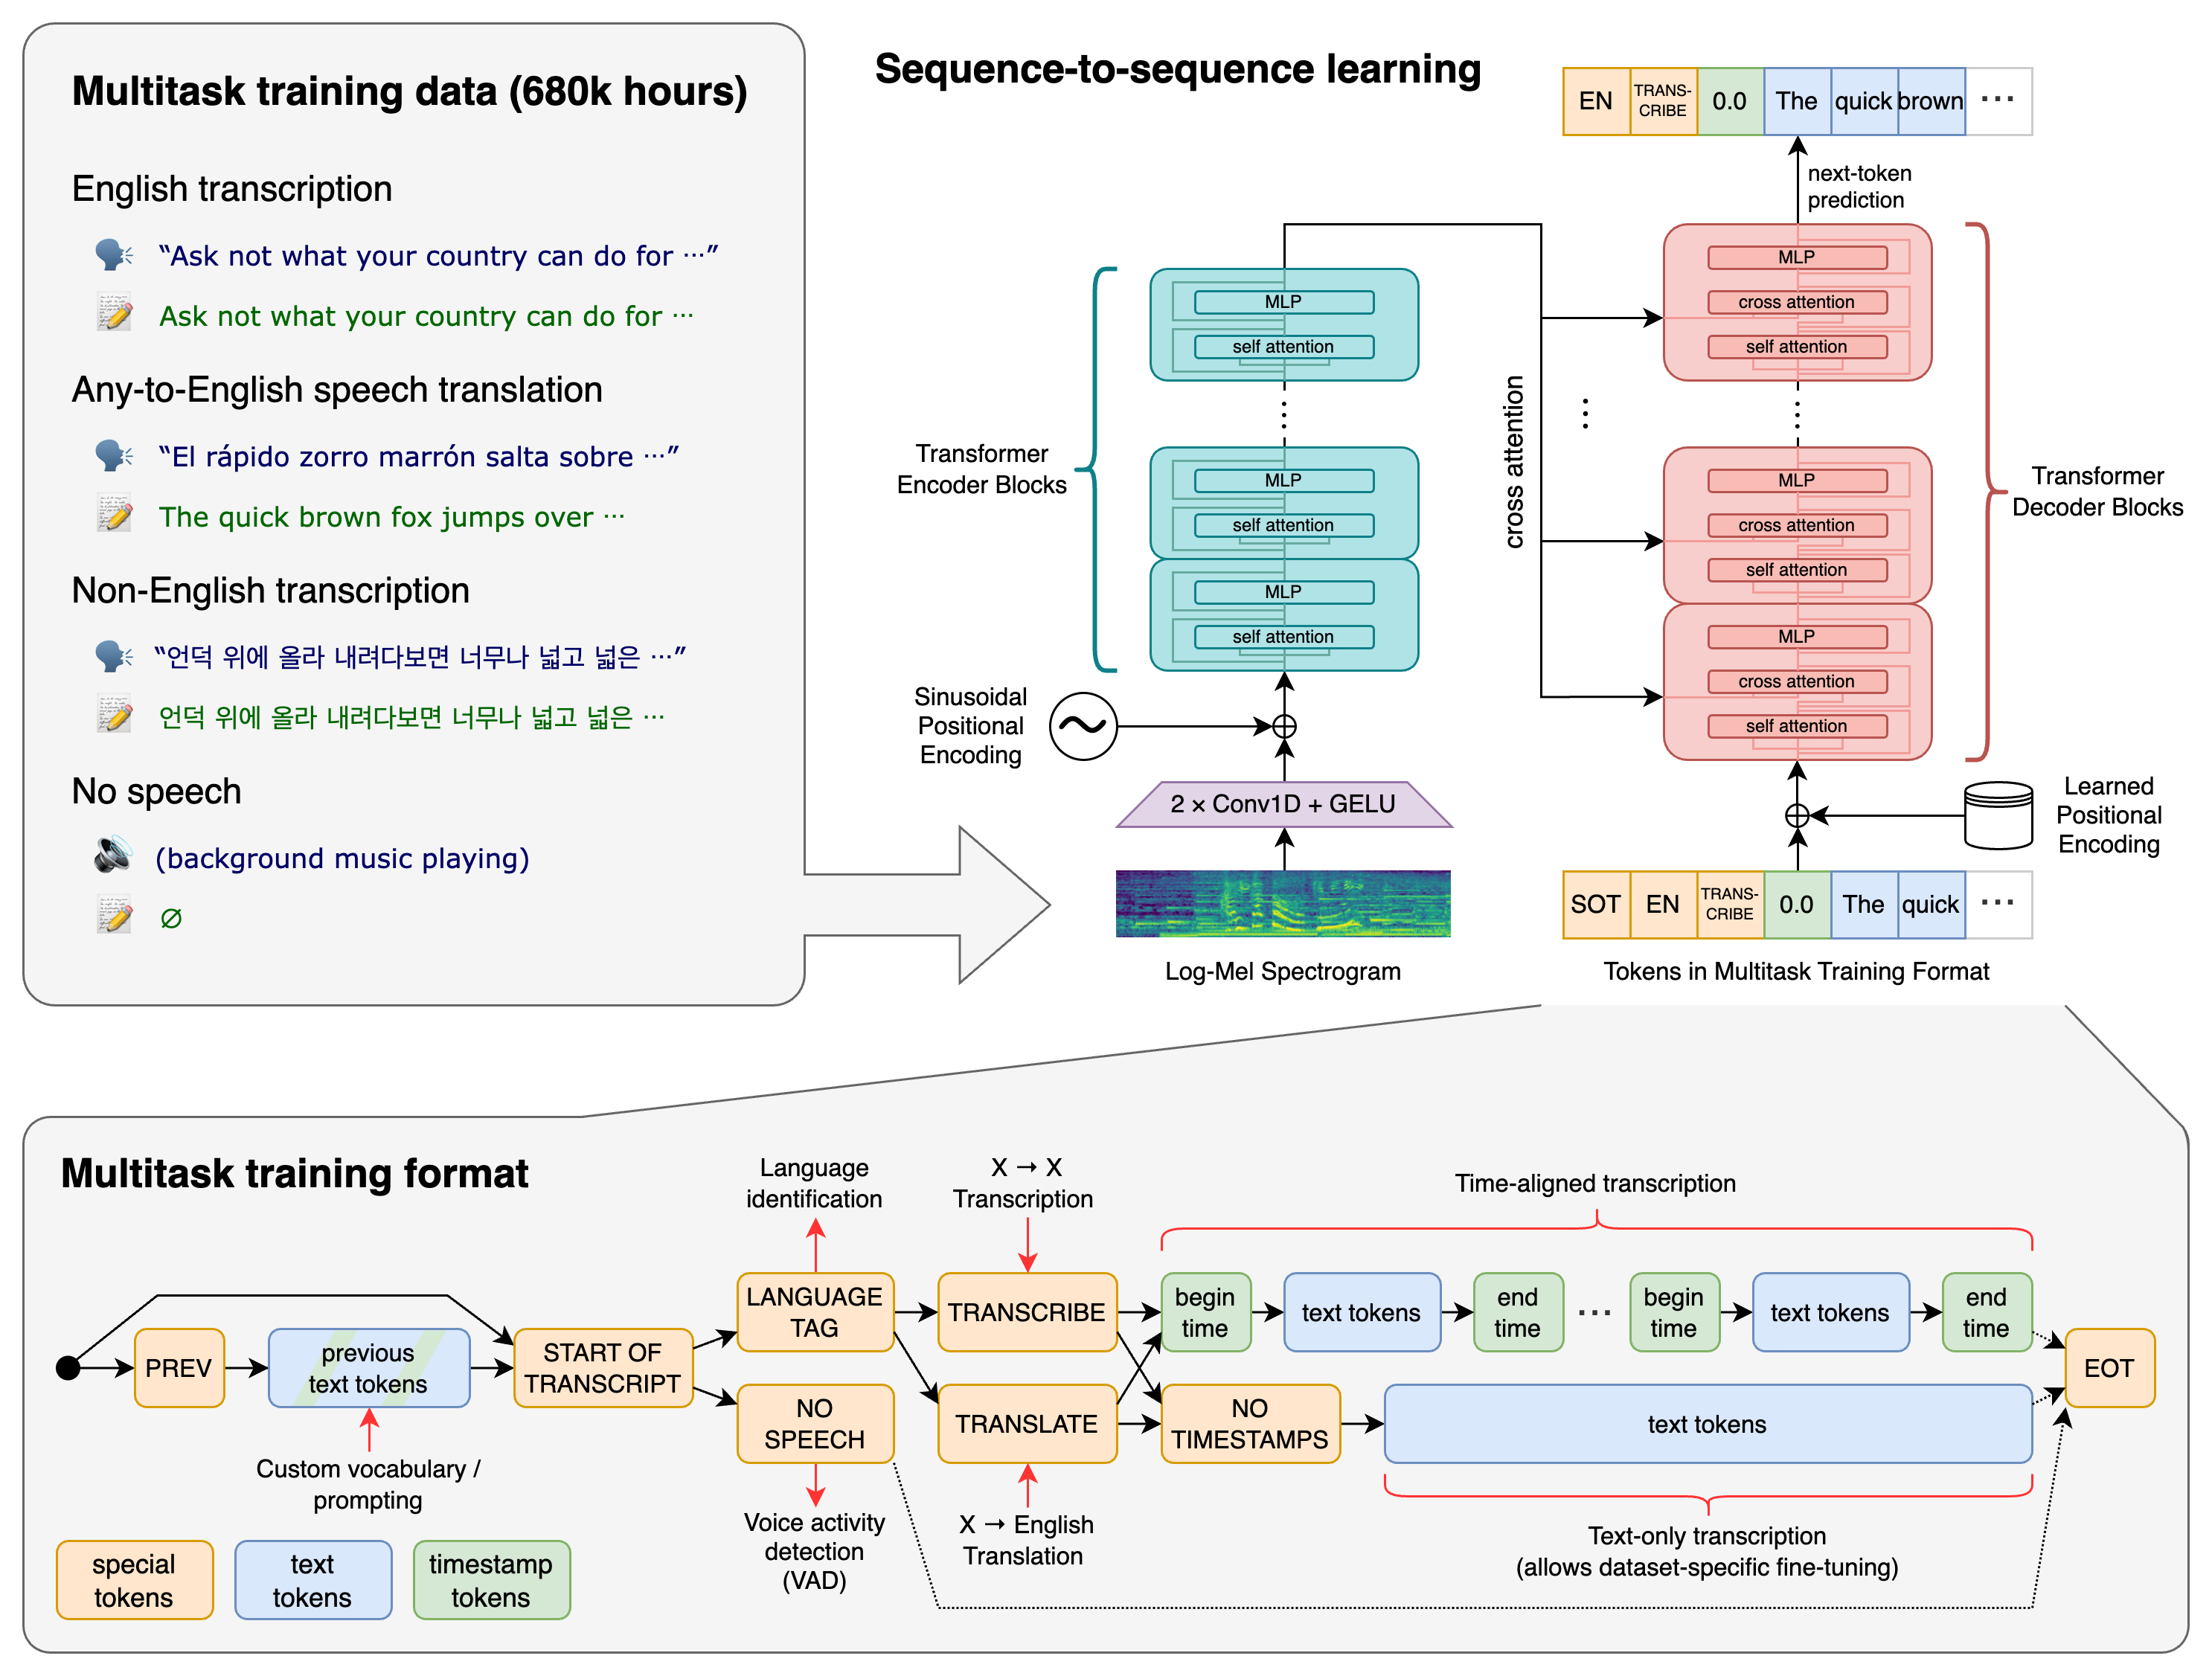
Multilingual transcription — Transcribes speech in 99 languages with automatic language detection.
Speech translation — Translates non-English audio into English text.
Multiple model sizes — Six model variants from 39M to 1550M parameters for speed and accuracy tradeoffs.
Task specification — Handles transcription, translation, language identification, and voice activity detection in one model.
Whisper is a production-grade speech recognition model trained on 680k hours of multilingual audio from the web. It handles accents, background noise, and technical language without fine-tuning. Works as both a Python library and CLI tool with multiple model sizes—use tiny for edge devices or large for maximum accuracy.
Requires ffmpeg and Python 3.8+. Optional: Rust for tiktoken compilation on unsupported platforms.
Source on GitHub
pavilion